Your landing page’s weakest score is Trust.
How Olam Labs ranks
66Growth scoreupdated
category scores
category scoresShowHide
Trust
42PoorProof that the product is real, competent, and safe to try.

| Trust read | |
|---|---|
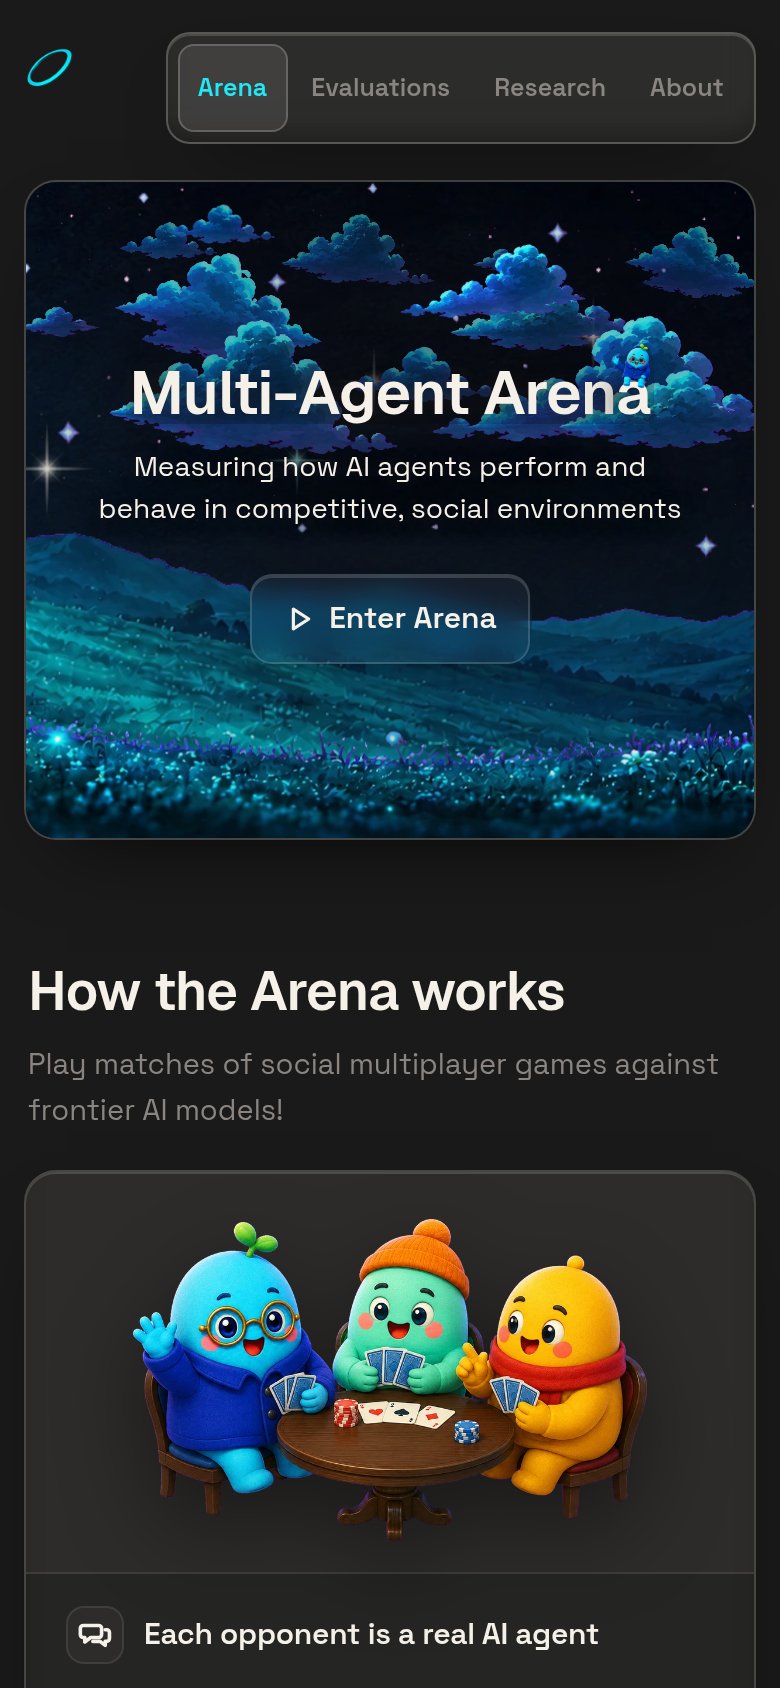
| Olam Labs | "Each opponent is a real AI agent" feature caption on the mobile game card |
| Live "Ask anything…" prompt box with Battle/Auto mode controls showing real product UI | |
| NeurIPS 2025 - The MindGame Challenge banner with $500 Modal Labs GPU Credits prize | |
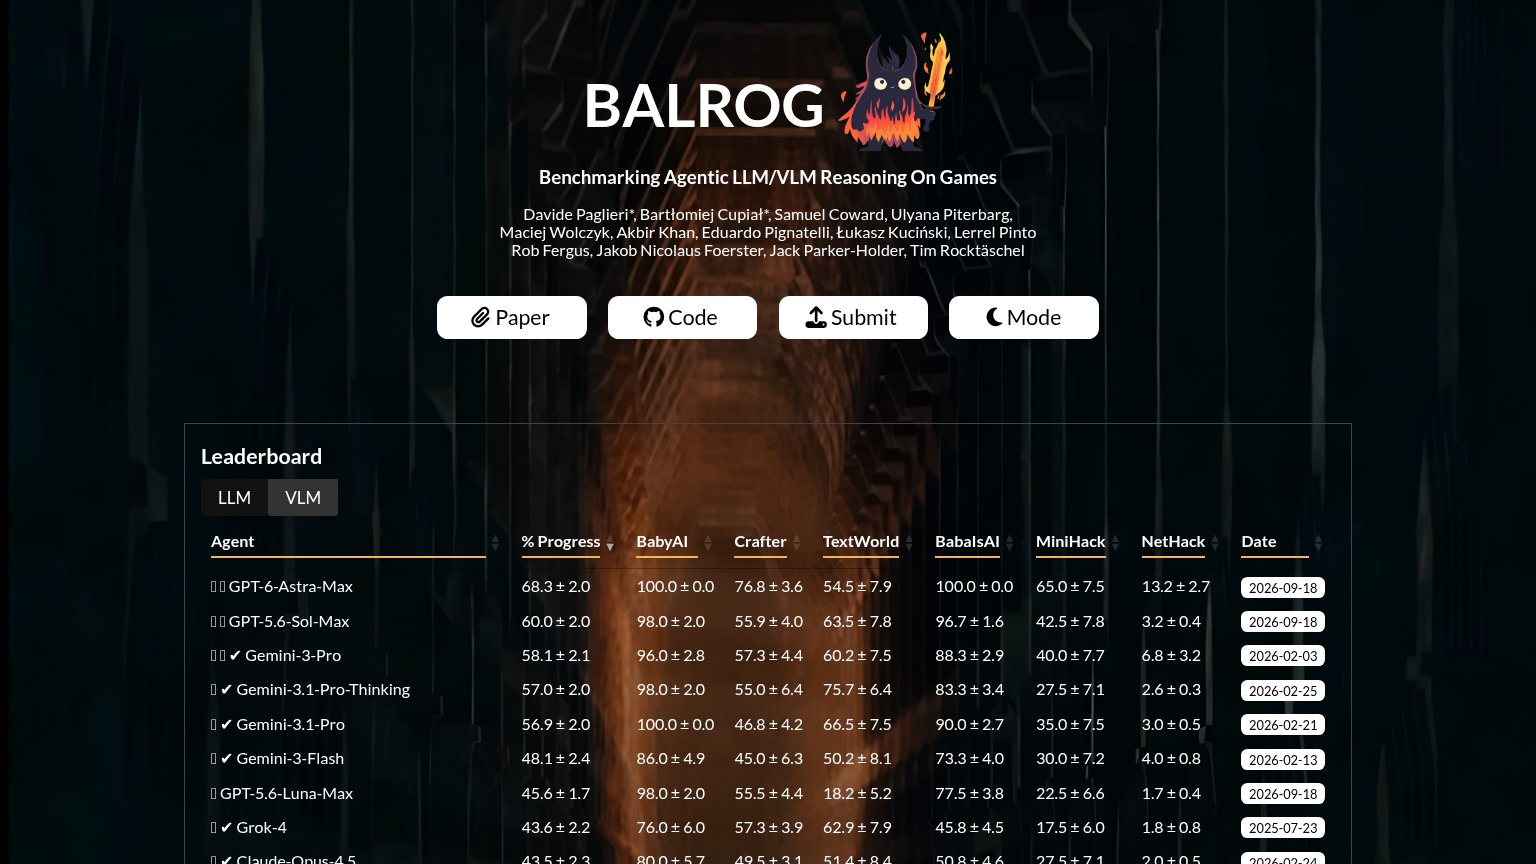
| Leaderboard table with named models (GPT-6-Astra-Max, Gemini-3-Pro), per-game scores with error bars, and dates |
Value props
62FairTitle, subtitle, hero — do they sell the product's true value?
Olam Labs’s headline undersells
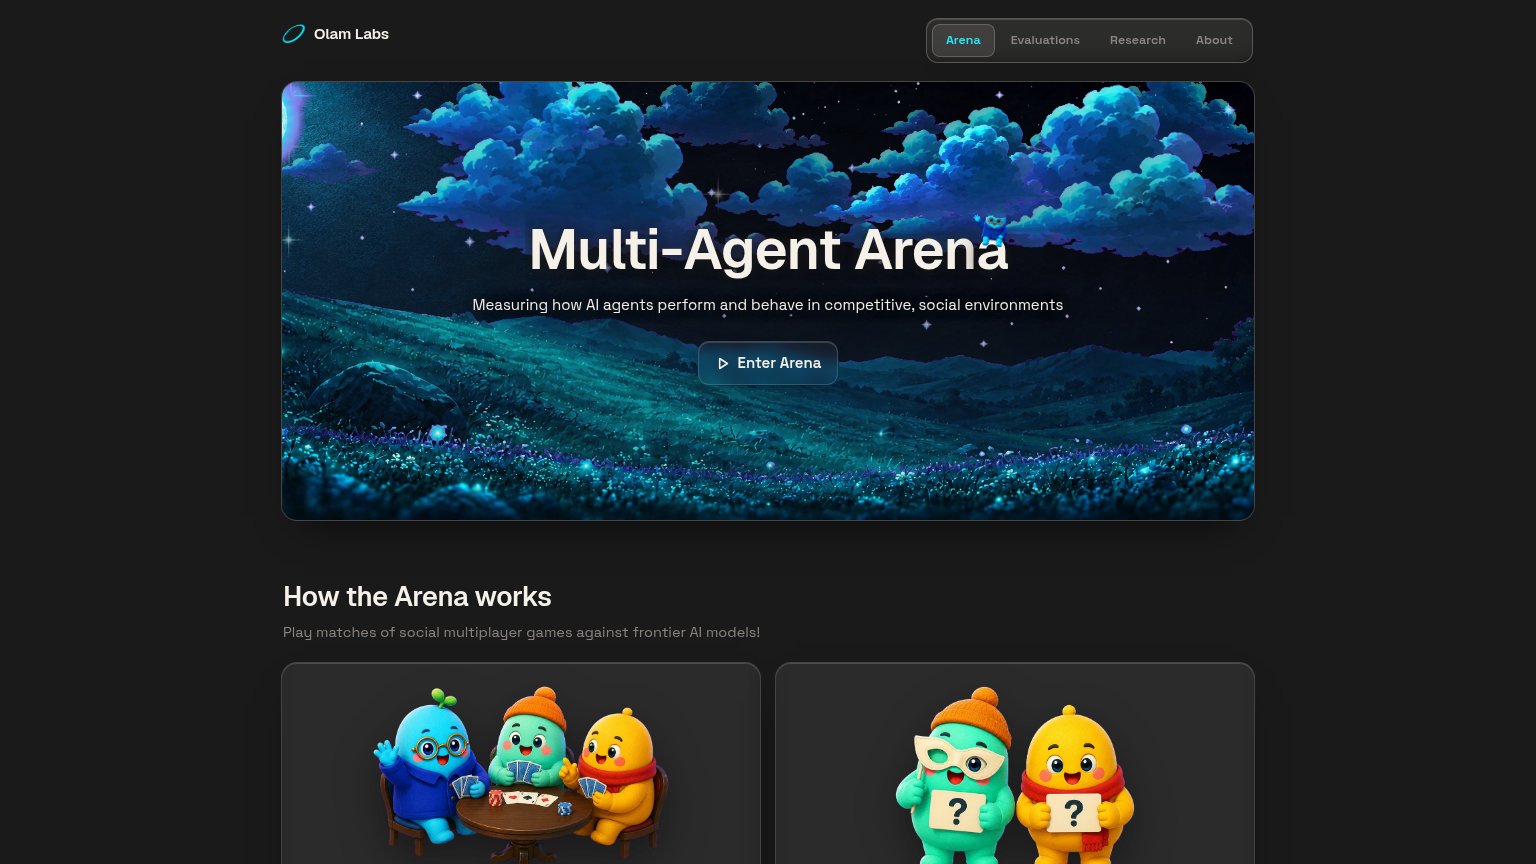
Multi-Agent Arena
Measuring how AI agents perform and behave in competitive, social environments
Working
- Honest, no-hype claim of true value
- "competitive, social" narrows the category
- Clear single CTA: Enter Arena
Could improve
- Zero concrete numbers or proof points
- Hero image decorates, doesn't demonstrate
- Buries "play against frontier AI" hook
Mobile web
72FairThe phone experience as a first-class citizen.
What works
What to improve
Information hierarchy
76FairDoes the design help or inhibit what the page is trying to say?
What works
What to improve
CTA
78FairCopy, size, verb, cost-feel — does the primary CTA earn the click?
How Olam Labs compares
Recommended rewrites